Observation, validity and reliability in practice
By UK GCSE Sociology · independent study · myAudience
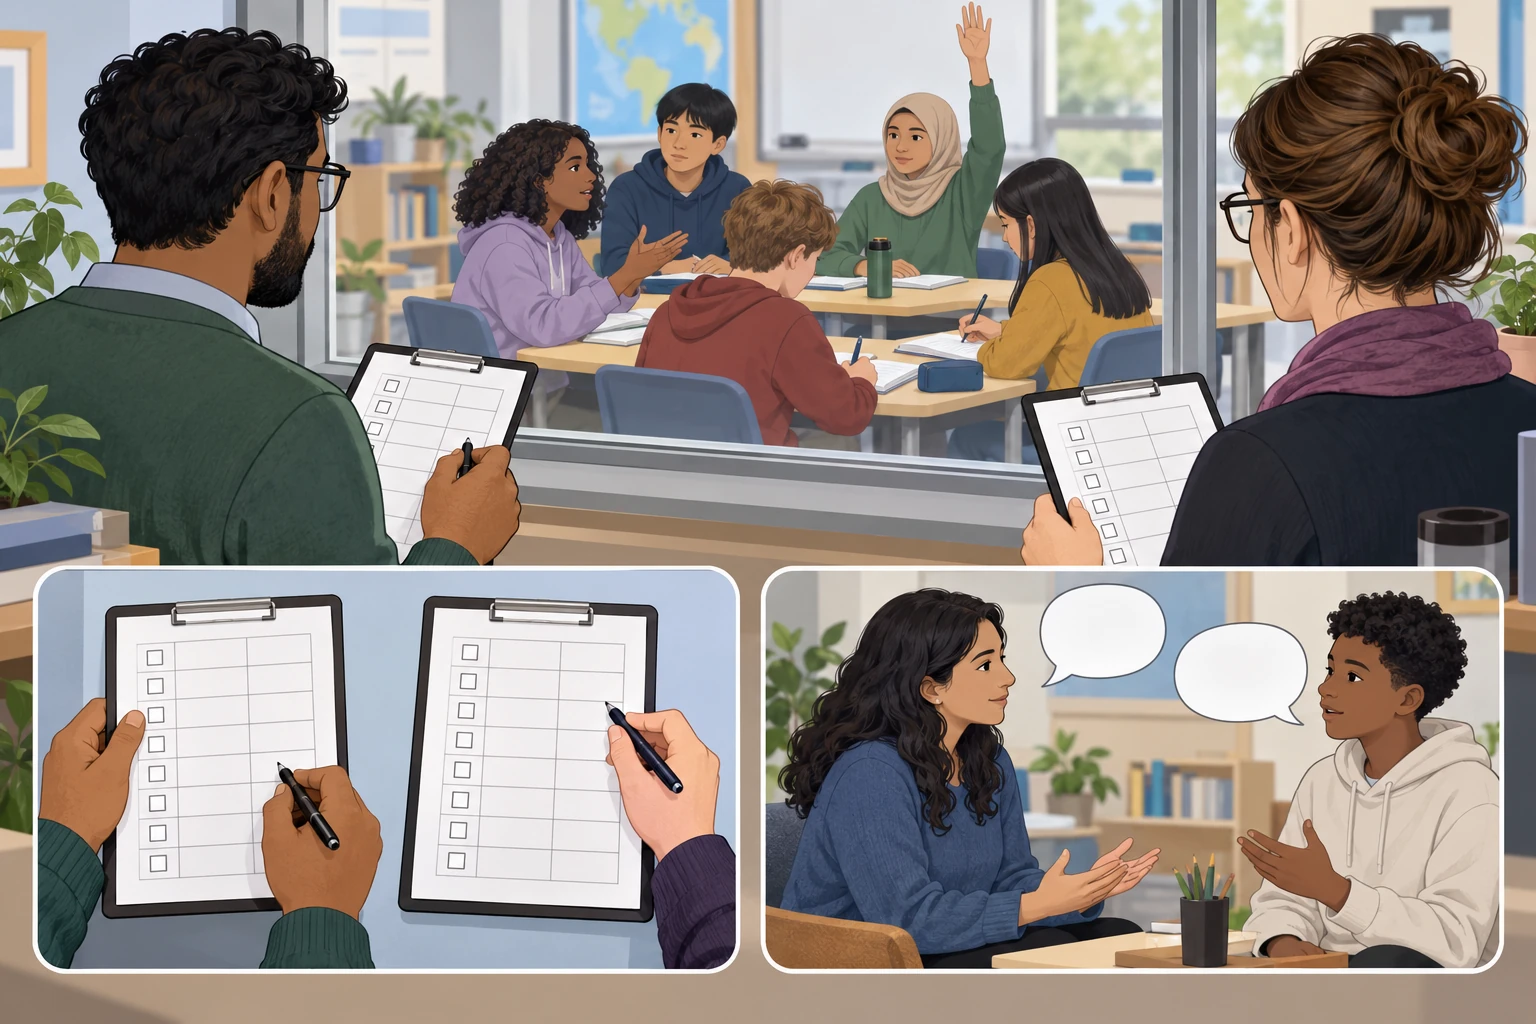
Original OpenAI imagegen conceptual teaching illustration, generated 4 October 2026; not observational evidence. · AI-generated original asset for this independent guide; no third-party artwork intentionally reproduced.
Observation, validity and reliability in practice
Observation records behaviour in a setting rather than relying only on what people later report. Participant observation involves the researcher taking part in the setting; non-participant observation involves observing without taking that participant role. Overt observation makes the research role known, while covert observation conceals it. These are different dimensions: a participant observer can be overt. Structured observation uses predefined categories; less structured observation develops detailed fieldnotes. The aim determines what is recorded, and each design creates different access, interpretation and ethical questions. Being present does not give direct access to another person's motives.
Reliability concerns consistency under appropriate comparable conditions. A clear coding rule can improve agreement between observers. If 'contribution' means any audible response, two observers may count similarly, while a vague instruction to record 'good participation' invites inconsistent judgments. Inter-observer agreement can be checked by coding the same event independently. Test-retest consistency requires caution when the underlying situation can genuinely change; different counts next week are not automatically unreliability. Record duration, setting and conditions so a reader can distinguish changes in procedure from changes in what is being observed.
Validity asks whether the evidence captures the intended phenomenon. Counting spoken turns may validly measure audible contributions, yet be a poor measure of understanding, engagement or influence. Some turns repeat others; silent learners may understand deeply. Two observers can agree perfectly on a narrow indicator and still miss the concept. Conversely, a nuanced account can reveal valid meanings while being difficult to reproduce word for word. Avoid a single ranking of 'good data': specify the particular measure and the conclusion it supports. Representativeness, introduced in lesson 05, adds another question about the cases and wider population.
Researcher presence can change behaviour: participants may perform an expected role when watched. This is often discussed as a Hawthorne or observer effect, but its existence and direction need evidence rather than automatic assumption. Longer observation may help researchers understand routine patterns, yet does not guarantee that reactivity disappears. Participant access can reveal context while creating role conflict and the risk of becoming so familiar that assumptions stop being questioned. Fieldnotes should separate observed events, participants' accounts and the researcher's interpretations. Reflexivity examines how the researcher's position and decisions shape knowledge.
Observation may show that a teacher invites one learner to speak repeatedly, but it cannot by itself establish why. Interviews, policy documents and comparison across lessons may help investigate explanations. Negative cases, such as a learner with the same label receiving different treatment, test the boundaries of an account. Covert research does not automatically produce more valid data and creates serious consent and privacy problems. Especially in settings involving children or sensitive relationships, 'natural behaviour' is not an adequate ethical justification. This guide uses hypothetical records and does not authorise classroom recording or covert observation.
The measurement illustration contrasts blank coding sheets with an interview. Read it as a question about evidence: agreement between sheets could suggest consistent coding, while conversation could clarify meaning. No scores or exact counts are encoded. It cannot establish either observer reliability or participant understanding. A useful evaluation ties one design feature to a consequence: predefined turns aid count comparison, but the indicator's narrowness limits inference about learning. Another feature may have an opposite trade-off. Good research criticism explains both gains and losses in relation to a particular aim.
Worked example: Original hypothetical coding record: for eight observed classroom events, Observer A codes participation as 1,1,0,1,0,0,1,0; Observer B codes 1,0,0,1,0,1,1,0. Calculate simple percentage agreement and evaluate a claim that the study therefore validly measures understanding.
Compare each paired event. They agree at events 1,3,4,5,7,8: six agreements from eight comparisons.
Compute 6/8 × 100 = 75% simple agreement. This is a descriptive check of these codes, not a chance-corrected coefficient or proof of population-wide reliability.
Review the disagreements and operational rule. Clarify whether writing or a nonverbal response counts, then trial the revised codebook without forcing agreement.
Separate consistency from validity: even perfect agreement about visible participation would not establish understanding. Seek a relevant indicator or account of understanding.
Answer: The observers agree on six of eight events, giving 75% simple agreement for this fictional record. That result provides limited evidence about coding consistency and identifies two events needing examination. It cannot prove that the indicator captures understanding, because visible participation and understanding are different concepts. A clearer codebook may improve reliability, while an appropriate learning task or voluntary account may help assess validity. The study must also explain why these events were selected and how researcher presence could affect behaviour. None of those questions is settled by the agreement percentage.
Check your understanding: Transfer task: a museum counts time visitors stand beside a display and calls it 'interest'. Evaluate one reliability improvement and two validity problems, then design a complementary method. Indicative rubric: 12 points: reliability 3, validity problems 4, complementary method 3, bounded conclusion 2.
Answer: Standardise when timing begins and ends and independently time the same fictional visits. Long duration could reflect waiting for a companion or difficulty reading rather than interest; brief duration could reflect prior knowledge rather than disinterest. A short voluntary interview could ask what the visitor noticed and why they stopped. It adds interpretation but also recall and interviewer effects. Report dwell duration as a behavioural indicator with limits, not a psychological diagnosis.
Why: The reliability change must improve consistency of the actual timing procedure. Validity criticisms must identify alternative meanings of the indicator, not only say the sample is small. The added method should address one of those problems and acknowledge its own limits. Claiming that the interview 'proves interest' would repeat the original inference error.